Published On:
April 22, 2026Last Updated:
October 9, 2026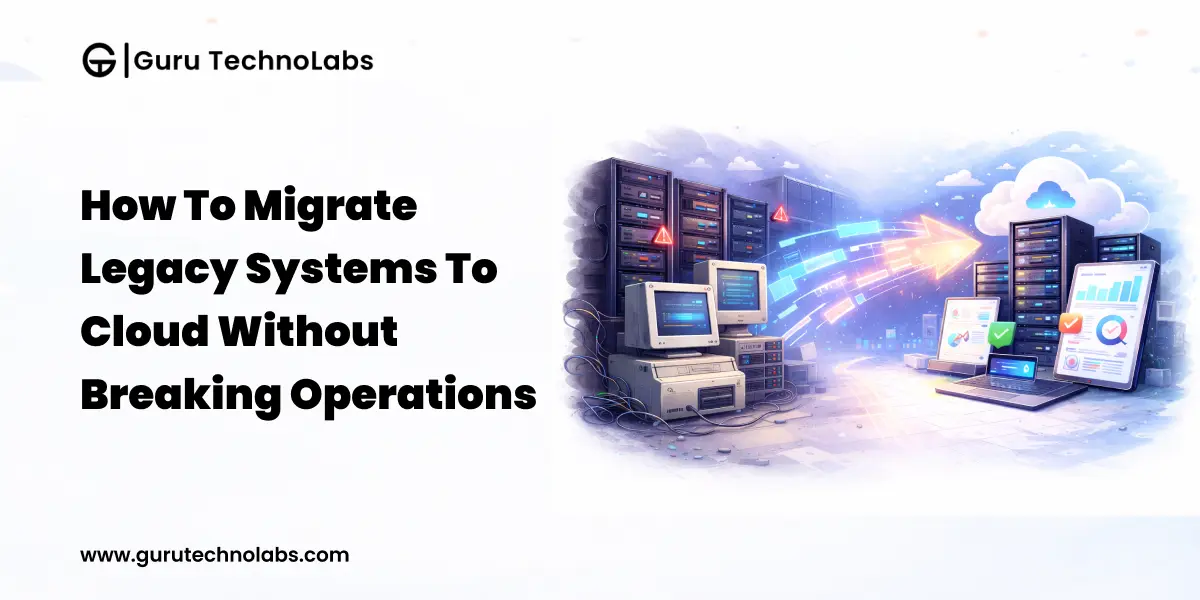
Legacy systems still power the most revenue-critical operations in most enterprises.
Legacy-to-cloud migration is the process of moving these on-premises applications, databases, and workloads to cloud infrastructure without disrupting the operations that depend on them.
Billing engines process millions of transactions per month. ERP platforms manage supply chains across geographies. Custom-built applications support entire business units daily.
These systems weren’t designed for cloud infrastructure, but the cost of keeping them on-premise is becoming increasingly difficult to justify.
The business case for legacy to cloud migration is clear:
However, what’s often underestimated is execution risk.
A failed legacy system migration to the cloud doesn’t just delay a project it can halt revenue-generating operations, break integration chains, and even trigger compliance violations in regulated industries.
Enterprises typically start asking about the best cloud migration services when legacy systems begin slowing operations, usually after the cost of delay is already visible. According to McKinsey, organizations that fail to plan for operational continuity often face 50–70% budget overruns and doubled timelines.
The root cause isn’t just technical complexity; it’s treating migration as an infrastructure task instead of a business-critical program.
The primary reason migrating legacy systems to cloud stalls isn’t technology it’s hidden complexity.
A monolithic application that appears to be a single system often contains layers of undocumented dependencies. These include inter-process interactions, database-level triggers that enforce business logic outside the application layer, and batch jobs running on schedules that haven’t been reviewed in years.
When teams begin to decompose these systems for cloud migration, they uncover coupling that was previously invisible. A billing module may directly query the inventory database. A reporting service might depend on a specific file system path for temporary storage. Authentication logic could be embedded in middleware that has no direct cloud-native equivalent.
This is why discovery and dependency mapping—before moving even a single line of code—typically takes 4–8 weeks for complex systems. Skipping or rushing this phase remains one of the most common causes of migration failure.
Every migration introduces a period of elevated operational risk.
During this phase, the organization operates in a hybrid state—some components remain on legacy infrastructure, while others run in the cloud, with integration layers bridging the two environments. At each of these intersections, risk compounds.
Lift-and-shift (rehosting) preserves all the inefficiencies of your legacy architecture while adding cloud costs on top because usage-based pricing punishes systems that can’t auto-scale. A monolithic application that once ran on fixed on-premises resources now runs on infrastructure billed by usage, so without auto-scaling, you end up paying for peak-capacity provisioning around the clock.
Teams choose rehosting anyway because it appears to minimize execution risk since the application itself stays unchanged; the assumption is that its behavior will stay consistent too.
AWS’s Well-Architected Framework explicitly cautions against this approach. Rehosting should be treated as a transitional step, not a final state.
More importantly, rehosting does not solve the scalability limitations that led to the migration decision in the first place. It simply shifts the same bottleneck to a different environment, without addressing the underlying constraints.
The most consequential mistake isn’t technical; it’s organizational.
When migration is owned solely by the infrastructure team, without a formal business continuity plan, no one is accountable for revenue impact. Operations, finance, and customer-facing teams must be involved in migration governance from the very beginning.
This requires defining acceptable downtime thresholds in business terms, such as revenue per hour, SLA penalties, and customer impact, and designing the migration architecture around those constraints, not the other way around.
Migrating an entire system in a single cutover significantly increases the blast radius.
If the cloud deployment encounters an issue during a late-night cutover window, the only options are to fix it under pressure or roll back the entire migration. For systems handling real-time transactions, the financial exposure from a failed big-bang cutover can reach six or even seven figures within hours.
Phased migration exists to eliminate this risk. While it may involve longer timelines and temporary parallel infrastructure costs, this approach is almost always less expensive than the impact of a single catastrophic failure.
Data migration is often the longest and most failure-prone workstream in any cloud migration.
Legacy databases typically contain years of schema drift, orphaned records, undocumented relationships, and business logic embedded in stored procedures. A migration plan that starts with “we’ll replicate the database” without auditing data quality, transformation requirements, and validation criteria is fundamentally flawed.
Organizations that underestimate this complexity frequently find data migration consuming 40–60% of the total migration timeline.
A rollback strategy that exists only on paper is not a real strategy.
Effective rollback capability requires maintained legacy infrastructure that can resume operations within the defined RTO (Recovery Time Objective), data synchronization mechanisms that support reverse replication from cloud to legacy, and DNS or routing configurations capable of switching traffic in under 60 seconds.
If rollback depends on manual coordination across multiple teams and takes several hours to execute, then your actual RTO is measured in hours – regardless of what the plan states.
Enterprise legacy systems rarely operate in isolation.
They are typically connected to 15–50 or more external systems through APIs, file transfers, message queues, database links, and EDI protocols. Each of these integrations represents a potential failure point during migration.
Organizations that fail to map the complete dependency graph upfront often discover critical integrations only after they break in production – simply because no one knew they existed.
If you’re looking to migrate a legacy system to the cloud securely, Guru Technolabs helps enterprises plan and execute cloud migrations with zero-downtime strategies tailored to complex, integration-heavy environments.
This section provides the architectural framework that makes safe migration possible. Every decision here directly impacts whether operations continue uninterrupted or face disruption.

When figuring out how to migrate legacy applications to the cloud, the fundamental mistake is applying a single migration strategy across all workloads. Each application should be evaluated independently based on four dimensions: business criticality, architectural complexity, available budget, and target timeline.
| Strategy | When to Use | Typical Timeline | Cost Profile | Risk Level |
|---|---|---|---|---|
| Rehosting | Low-complexity apps, time-sensitive datacenter exits, compliance-driven moves | 2–8 weeks per application | Low upfront; higher long-term operational cost | Low execution risk; high technical debt risk |
| Replatforming | Apps needing targeted optimization (e.g., database swap to managed service, containerization) | 4–12 weeks per application | Moderate; balanced ROI within 12–18 months | Moderate; requires architectural analysis |
| Refactoring | Business-critical systems requiring scalability, performance, and long-term extensibility | 3–9 months per application | Highest upfront; lowest long-term TCO | Highest execution risk; highest strategic value |
Most enterprise migrations use a combination of all three. A typical portfolio might rehost 40% of applications (low-criticality workloads), replatform 35% (mid-tier business applications), and refactor 25% (core revenue-generating platforms). For a detailed comparison of rehosting, replatforming, and refactoring approaches, evaluate each workload against these criteria before committing to a strategy.
Phased migration enables organizations to move legacy systems to the cloud without shutting them down.
Instead of a single high-risk cutover, the system is decomposed into functional domains. Each domain is migrated independently and fully validated before moving to the next.
The sequencing logic is critical:
In many enterprise cases, this phase is where organizations require structured execution support from planning workloads to designing scalable environments, which is where working with a team experienced in cloud app development can significantly reduce long-term architectural risks.
For systems where downtime directly impacts revenue, the dual-run strategy provides the strongest assurance of operational continuity.
In this approach, both the legacy system and the cloud system process live transactions simultaneously. A comparison engine validates outputs in real time, flagging discrepancies immediately. Traffic continues to flow through the legacy system until the cloud environment consistently demonstrates accuracy.
The dual-run period typically lasts between 2–6 weeks for transactional systems. While this temporarily doubles infrastructure costs, the trade-off is justified.
For example, in a billing platform processing $10M+ per month, the cost of maintaining parallel infrastructure for a few weeks is negligible compared to the financial impact of even a single day of billing errors.
How to migrate legacy databases to the cloud comes down to one thing: data migration requires a dedicated architecture and execution strategy.
For data-heavy enterprise environments, data migration alone can account for 40–60% of the total timeline. Systems with 5–10TB of structured data and complex transformation requirements typically require 8–16 weeks for migration and validation.
During phased migration, systems operate in a hybrid state—some components remain on legacy infrastructure while others run in the cloud.
The integration layer ensures these components function together as a cohesive system.
Proven architectural patterns include:
Migration testing is not a single phase – it is a continuous discipline applied throughout the process.
Rollback is not a document – it is an architectural capability.
Critically, rollback must be tested before it is needed. Conduct a full rollback drill during the pilot phase. If execution exceeds your target RTO, refine the process before migrating any mission-critical systems.
Migration is not the finish line – it’s the beginning of operating in a fundamentally different model.
The first 90 days after migration are critical. This period establishes the operational disciplines that determine whether the cloud delivers on its promised benefits.
Auto-scaling policies should be configured based on real production data, not assumptions.
Scaling triggers must align with business-relevant metrics – such as transactions per second or queue depth – rather than relying solely on infrastructure indicators like CPU utilization.
Architectures should prioritize horizontal scaling by adding instances instead of increasing instance size. This approach reduces the risk of single points of failure and improves overall system resilience.
For read-heavy workloads at scale, use read replicas and connection pooling to prevent database saturation during traffic spikes. Cloud databases behave differently from on-premises systems under load, especially as concurrent connections increase.
For globally distributed applications, consider multi-region database architectures. However, ensure eventual consistency trade-offs are clearly defined and communicated to business stakeholders.
Baseline performance metrics should be established within the first two weeks after migration and monitored continuously.
Key metrics to track include:
Without proper governance, cloud costs can exceed on-premise expenses within 6–12 months.
The cost of migrating legacy systems to the cloud extends beyond the migration itself—it includes ongoing operational spend.
To control costs effectively:
Our cloud engineers specialize in building architectures that scale with your business without runaway costs. Let’s discuss your infrastructure requirements and design a cloud-native roadmap.
Every cloud environment provisioned during migration should be defined in code using tools such as Terraform, CloudFormation, or Pulumi.
This approach ensures that environments are reproducible, auditable, and can be provisioned or decommissioned in minutes. It also eliminates configuration drift, which is a common source of instability in manual setups.
CI/CD pipelines should automate the build, testing, and deployment processes for every migrated component. By removing manual intervention, organizations reduce the risk of human error and accelerate delivery timelines.
Traditional threshold-based alerting often generates excessive noise and fails to capture emerging issues.
Modern observability platforms leverage anomaly detection to identify patterns that static thresholds cannot detect. For example, a gradual increase in latency may indicate database connection pool exhaustion, while specific error patterns may correlate with an integration partner’s maintenance window.
This proactive detection enables teams to address issues before they escalate into production incidents.
Machine learning models can significantly accelerate the discovery phase of migration.
By analyzing legacy codebases, these tools can identify component boundaries, map dependency relationships, and highlight potential migration candidates. While they do not replace architectural expertise, they provide valuable insights that improve planning accuracy.
In large-scale environments, AI-assisted analysis can reduce discovery timelines by 30–40%. As a result, organizations investing in broader digital transformation initiatives are increasingly integrating AI-driven tools into their migration planning workflows.
This framework represents an execution sequence that consistently delivers successful outcomes in complex enterprise environments:
Step 1 – Discovery and assessment
Map the complete application portfolio, dependency graph, data landscape, and integration inventory. Define business criticality tiers. This phase typically takes 4–8 weeks in complex environments and has a direct impact on overall migration quality.
Step 2 – Define success criteria
Establish quantitative migration goals, including target latency, uptime SLAs, cost per transaction, and time to recovery. These metrics become the validation gates for all subsequent phases.
Step 3 – Select strategy per workload
Apply the rehost, replatform, or refactor decision framework to each application individually. Document the rationale to ensure stakeholder alignment.
Step 4 – Design target architecture
Define cloud infrastructure, networking, security boundaries, integration layers, and the observability stack. The architecture must support both the hybrid migration phase and the final end state.
Step 5 – Build a data migration plan
Audit data, define transformation and cleansing requirements, select replication tools, and design the validation framework. Data migration should begin early and run in parallel with application migration.
Step 6 – Execute pilot migration
Migrate a non-critical workload end-to-end. Validate infrastructure, deployment pipelines, monitoring systems, and rollback procedures. Document key learnings—this pilot helps de-risk all subsequent phases.
Step 7 – Phased production rollout
Execute migration according to the planned sequence. Apply dual-run validation for critical systems, ensuring each phase meets its validation criteria before progressing to the next.
Step 8 – Stabilize and optimize
Monitor performance, cost, and reliability for 60–90 days post-migration. Right-size resources based on actual utilization. Decommission legacy infrastructure only after stability is fully confirmed.
For enterprise-scale migrations involving 20 or more applications with complex integration dependencies, the complete lifecycle – from discovery to legacy decommission – typically spans 9-18 months.
A well-structured cloud migration strategy reduces timelines not by accelerating execution, but by minimizing rework caused by inadequate planning.
A mid-market travel technology company operating a legacy booking platform built on a monolithic Java application with an Oracle database was experiencing significant system degradation during peak booking seasons.
Transaction failures during high-traffic periods resulted in an estimated loss of $200K+ per quarter due to failed bookings and increased customer churn.
The migration followed the phased approach outlined earlier:
Outcome:
Total migration timeline: 18 weeks, from initial discovery through to legacy system decommissioning for the core platform.
Legacy system migration to the cloud is primarily about protecting ongoing business operations not simply moving technology.
Technology decisions such as rehosting versus refactoring, batch versus real-time data migration, and API gateway versus message broker are important, but they are secondary to strategic choices. The real impact lies in how migration is sequenced to protect revenue, how each phase is validated before proceeding, and how effectively the organization preserves the ability to reverse course if necessary.
Organizations that consistently deliver successful migrations follow a clear pattern: they invest heavily in discovery, planning, and testing. They accept longer timelines in exchange for reduced risk. And they view the dual-run validation period not as overhead, but as a critical safeguard against operational disruption.
Safe migration is driven by strategy, not speed.
At Guru TechnoLabs, we help enterprises migrate legacy systems with a core focus on business continuity, sequencing change to unlock cloud benefits while safeguarding operations. For complex, integration-heavy environments, the best time to begin planning is before urgency dictates concessions.
Legacy system cloud migration is the process of moving applications, data, and workloads from on-premise infrastructure to cloud environments. The goal is to improve scalability, reduce operational costs, and enable modern capabilities without disrupting existing business operations.
Migration carries risks such as downtime, data loss or inconsistency, integration failures, and performance issues. These risks increase when systems are monolithic, tightly coupled, or lack proper documentation, making careful planning essential.
Migration timelines depend on system complexity, data volume, and strategy. Simple rehosting can take a few weeks, while enterprise-level migrations involving refactoring and complex data movement typically take 6 to 18 months.
Yes, using a dual-run (parallel) approach allows both systems to operate simultaneously. This ensures real-time validation, reduces risk, and provides a fallback option to maintain business continuity.
Yes, but it can be minimized or avoided. Downtime usually occurs due to poor planning, limited testing, or missing rollback strategies. A phased migration with parallel system execution can help achieve near zero-downtime for most enterprise systems.
Secure migration requires three controls working together:
Pair these with a phased migration and dual-run validation, so security checks happen at every phase, not just at final cutover.
Evaluate migration services on four criteria:
Services that skip any of these tend to produce the 50–70% budget overruns McKinsey associates with poorly planned migrations.
Start by auditing what you actually have. A good chunk of legacy data, often 30–50%, can just be archived instead of dragged along into the new system. If downtime isn’t an option, skip batch transfers and use continuous replication tools like AWS DMS, Azure Database Migration Service, or Google’s equivalent, so data stays in sync while both systems run side by side. Once it’s moved, don’t assume it’s correct; check row counts, run checksum comparisons, and confirm things like account balances actually match between old and new.
To sync legacy databases to the cloud, use continuous replication tools like AWS DMS, Azure Database Migration Service, or Google’s version to keep your legacy and cloud databases updated in near real time while both are running at once. That’s the piece that actually makes zero-downtime cutovers possible: writes on both sides stay lined up, so you’re not stuck choosing a moment to “flip the switch”; traffic can shift over once you’re confident the cloud side is accurate.
Read more on:
Cloud
Ravi Makhija is the Founder and CEO of Guru TechnoLabs, an IT services and platform engineering company specializing in Web, Mobile, Cloud, and AI automation software systems. The company focuses on building scalable platforms, complex system architectures, and multi-system integrations for growing businesses. Guru TechnoLabs has developed strong expertise in travel technology, helping travel companies modernize booking platforms and operational systems. With over a decade of experience, Ravi leads the team in delivering automation-driven digital solutions that improve efficiency and scalability.


Share your business needs or project requirements with us & we will get back to you quickly.